Enterprise Kubernetes distribution
Bahriya Kubernetes Engine. A distribution that makes exactly two decisions.
The network fabric and the Kubernetes version, pinned to the exact patch. Everything above them — ingress, API gateway, storage, metrics, monitoring, service mesh, log shipping — is yours to enable (with a single flag).
self-service · no sales call · no payment details · one command per node
The engine behind bahriya.cloud — our own public cloud, in production across multiple regions.
The argument
Most distributions are platforms wearing a distribution's name.
OpenShift, Rancher and Tanzu decide your storage, your ingress, your mesh and your monitoring before you arrive. Each of those decisions is one you still operate and still pay for, whether or not it suits your estate — and when it does not, you run a second ingress beside the one you were given and investigate every failed request twice.
BKE does not put you there, because it never makes that choice on your behalf. It decides the network fabric and the Kubernetes version. You decide the rest.
The two decisions
Both pinned. Both fixed for the life of the cluster.
Decision I
The network fabric
Calico, at an exact patch we have tested against everything else in the release. The fabric is the one layer nothing above can route around, so it is the one layer a distribution must own.
Decision II
The Kubernetes version
Upstream Kubernetes, no fork, no proprietary CRDs — pinned to the exact patch. Upgrades move one version at a time; a non-adjacent jump is refused, not warned about.
Everything above them is enabled, not endured.
components.<name>.settings.enabled: true — one line eachThe licence gates BKE, not parts of it.
Determinism
The same version installs the same cluster. Twice.
A release is a set of promises about which versions work together. BKE keeps those promises mechanical rather than aspirational.
exact-patch pinning
Nothing floats.
Two installs of one BKE version, two months apart, produce the same cluster — not whatever upstream happened to publish that morning.
mirrored artefacts
Every chart and image, held by us.
A release installs from artefacts we mirror and serve. An upstream registry outage, rename or retag cannot change what your cluster runs.
blast radius
Upgrades are classified before they run.
Every upgrade declares what it will touch. A patch never drains a node; anything that would is named as such before you commit to it.
configuration you own
Your values are a file, and the diff waits for you.
Every component's configuration is a file you own and may edit; upgrades show you the difference between yours and ours, and wait for you to agree. The Passage Plan →
The Passage Plan
Every upgrade, laid out before it runs.
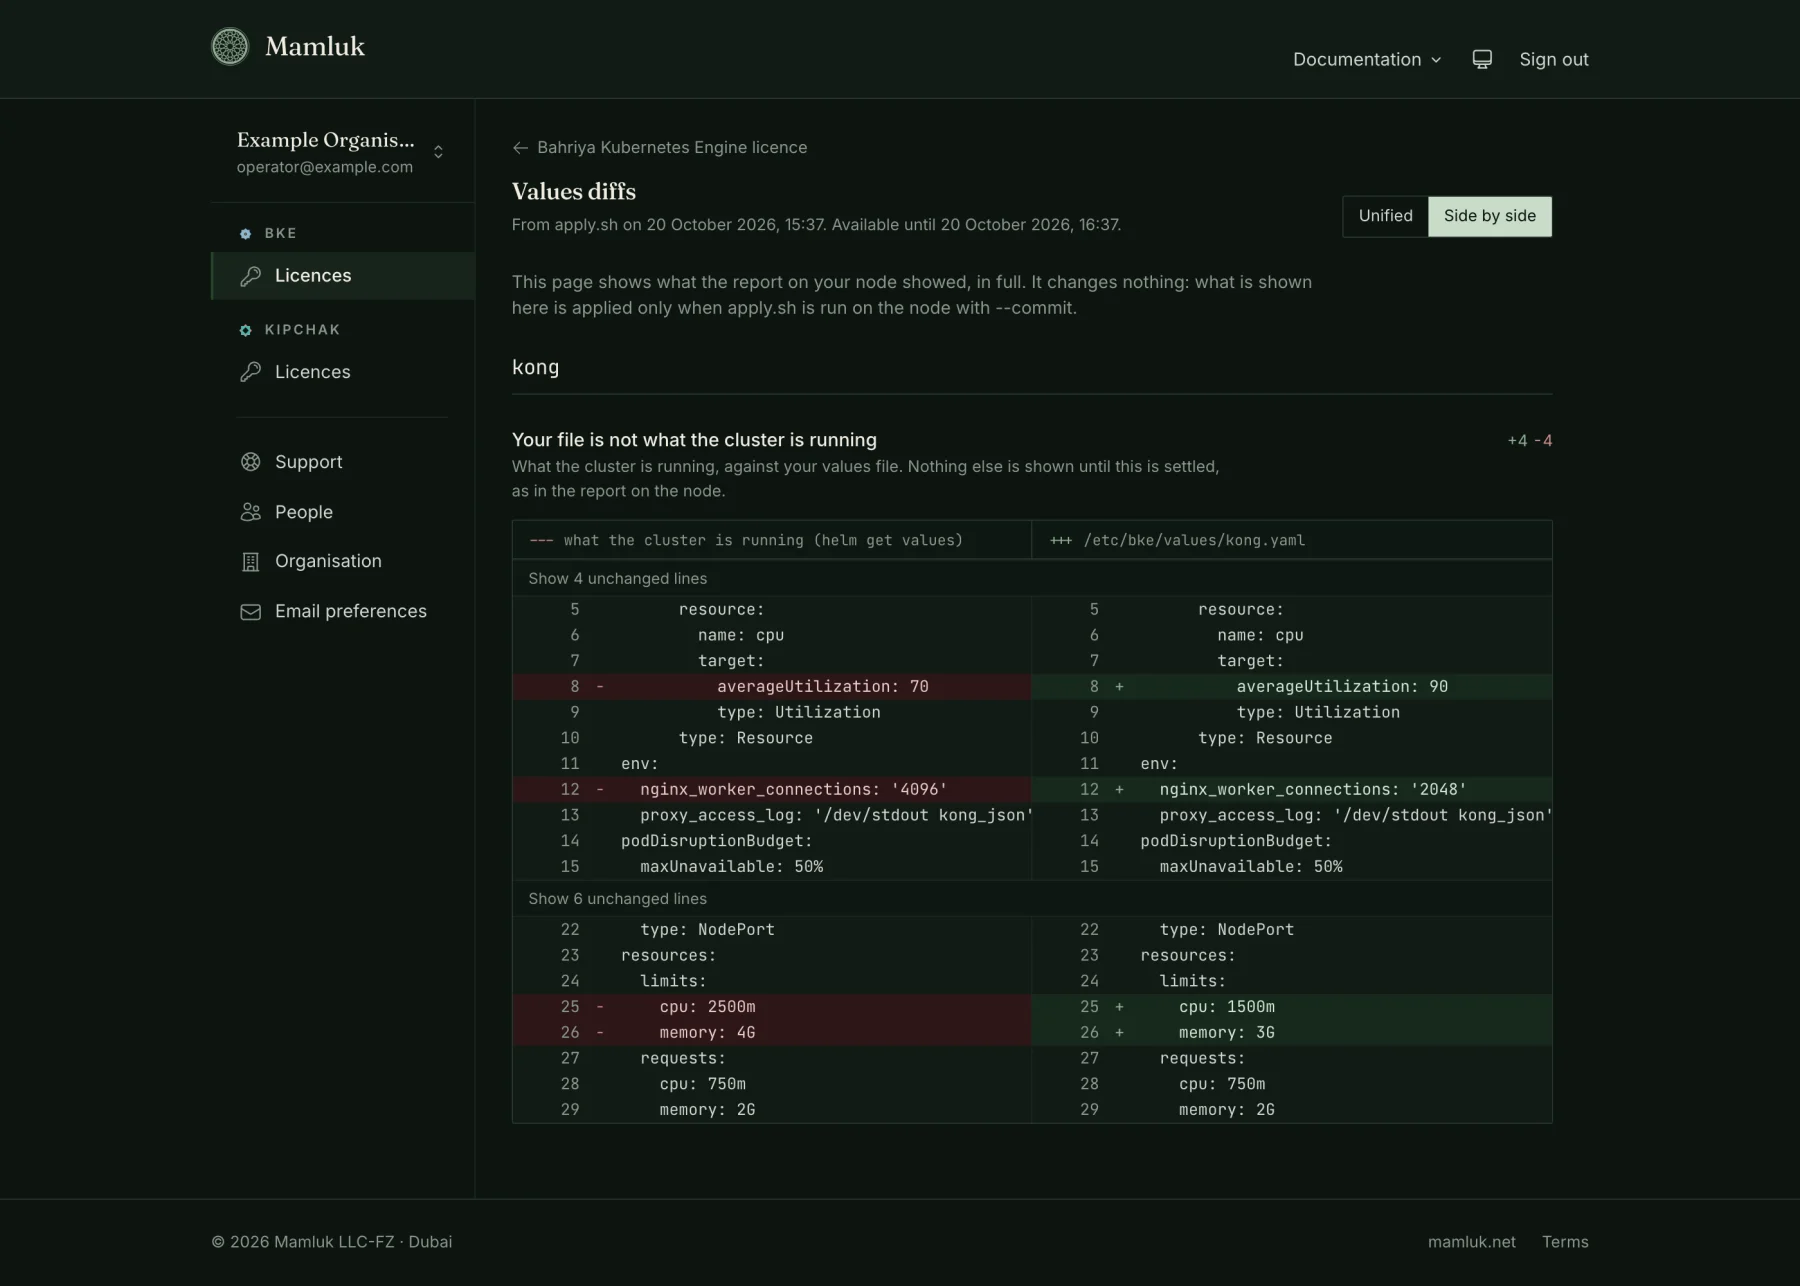
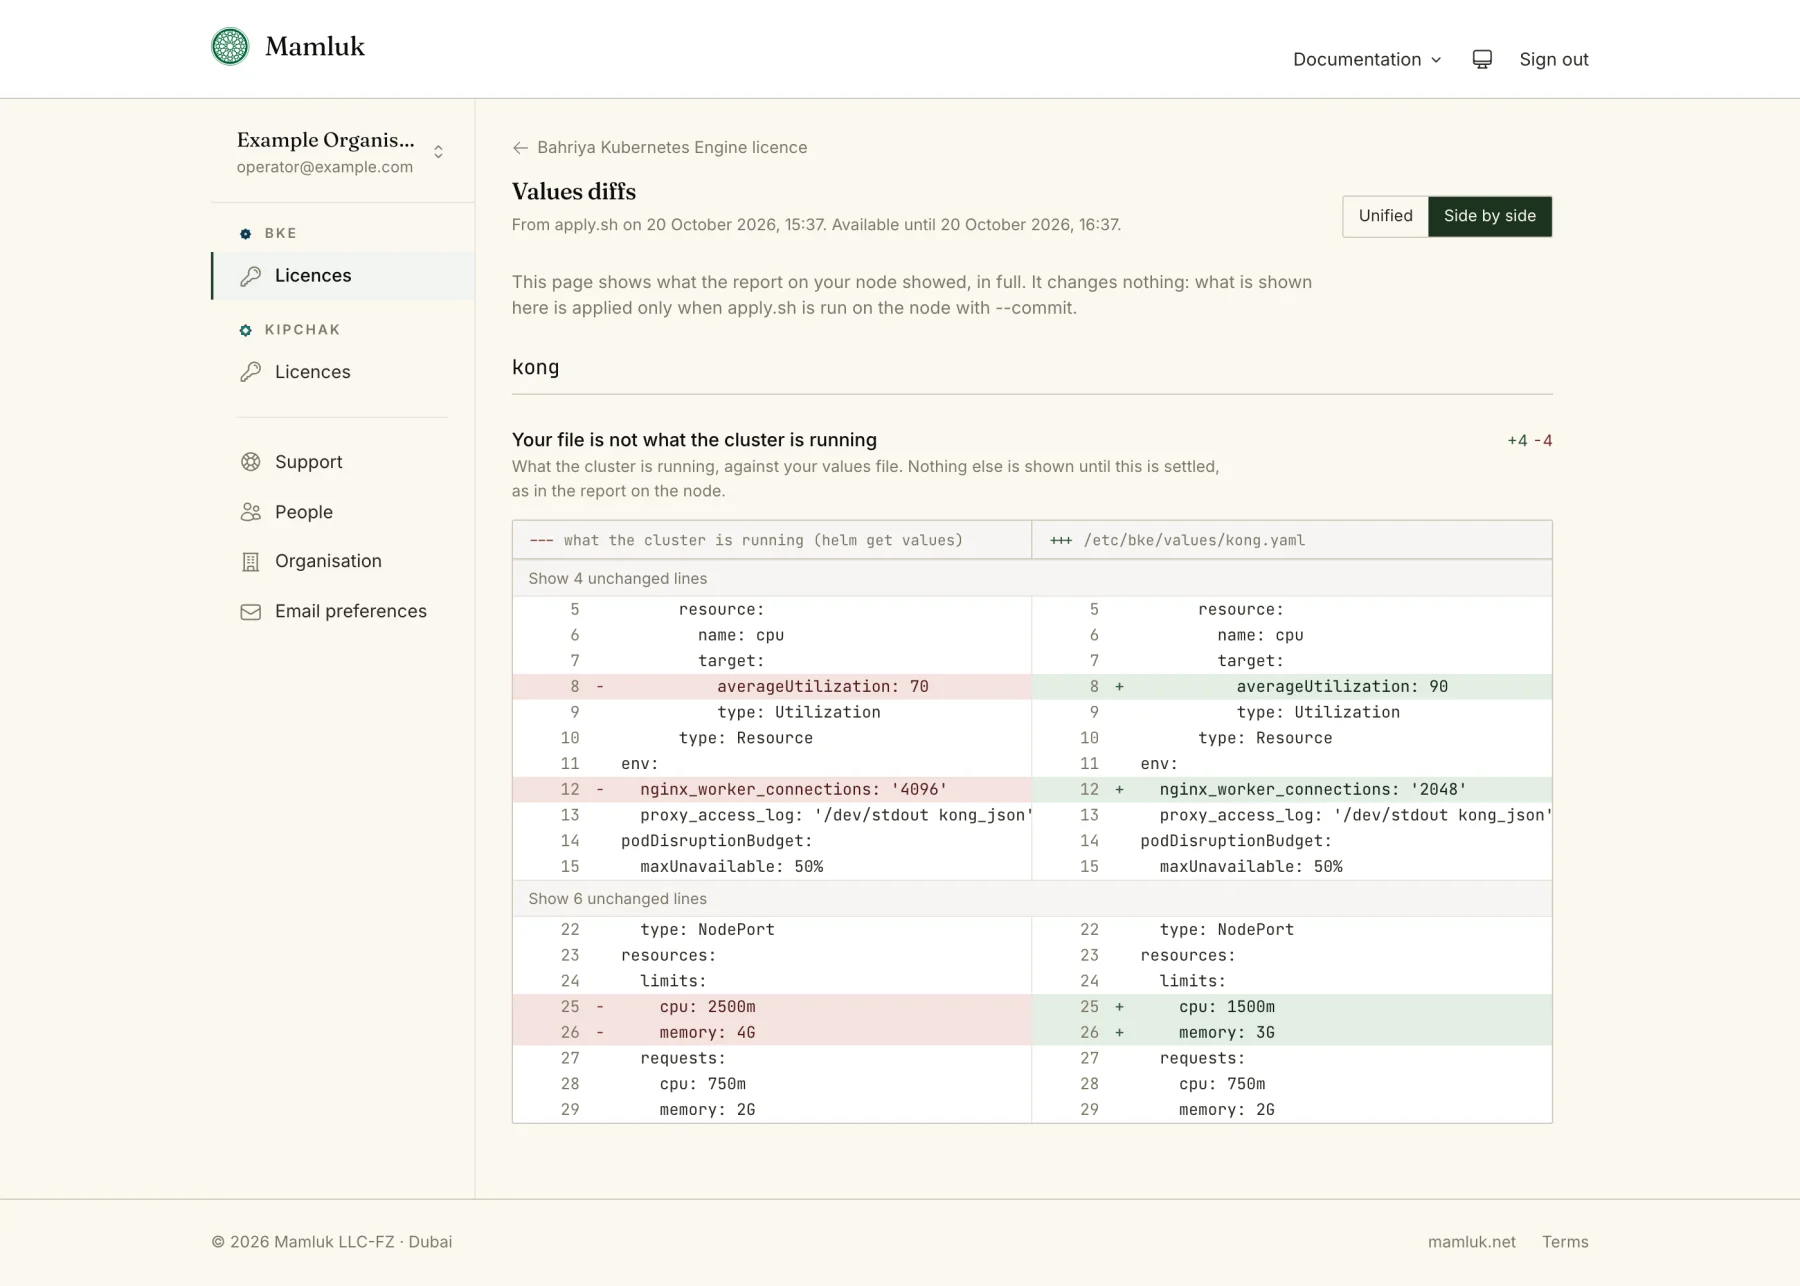
Before BKE changes a component's configuration, it reports what would change and stops. The Passage Plan is that report in the console: every diff, in full and in colour, for anyone in your organisation to read before anyone commits to it.
- What BKE changed, and what that means for your file, shown separately.
- Your edits stand. A conflict stops the run; so does a change made by hand.
- Encrypted, with a key we do not keep, and gone in an hour.
The platform step
A cluster when you want a cluster. A platform when you want more.
BKE is deliberately not a platform — that is the point of it. But a platform is one pairing away, and it is a pairing we run ourselves.
BKE
The engine.
Two decisions, pinned to the exact patch: the network fabric and the Kubernetes version.
BKE bundled components
A production cluster.
Storage, ingress, certificates, mesh and observability — enabled one line each, only the ones you want.
Bahriya Tersane
A platform.
Production Helm charts and operators for the data stores, messaging, identity, registry and CI above the cluster, with the operational decisions already made.
That pairing is what runs bahriya.cloud — the ground OpenShift occupies, assembled from parts you can name, version and keep. How the platform step works → Visit tersane.bahriya.cloud →
Ownership
Nothing of ours sits in your data path.
The licence gates install and upgrade. Nothing else.
A running cluster keeps serving if the licence lapses or we are unreachable. There is no callback in the request path, no agent that production waits on.
Reporting is declared, small, and gates nothing.
What a cluster reports is a short, published list of fields. It exists so your console can show you your own estate — it is telemetry, never permission. Every field, listed →
Support by ticket, wherever you run.
Support is ticket-based with a 24/7 tier available — and because nothing in production ever waits on us, a ticket is about progress, not permission. Delivered by Mamluk, the engineering practice that builds BKE.
BKE is not a product we assembled to sell. It is the engine our own public cloud runs on, licensed for your data centre.
in production at bahriya.cloud
Pricing
One flat fee per cluster. The end of the arithmetic.
OpenShift and Tanzu are licensed per core, which is why their quotes grow every time your cluster does. BKE is licensed per cluster, whatever its size — add capacity and the licence does not move.
Put in the unit your other quotes arrive in: on an eleven-node reference cluster, the flat fee works out to US $83.33 per worker core. Substitute the rate from the quote in front of you and compare.
See the worked example →Three clusters on OpenShift and on BKE →
GET mamluk.net/data/bke-pricing.json
US $12,000
Flat. Irrespective of node count, CPU or memory. Support & maintenance contracts on request.
The field
Named comparisons, not a feature matrix.
Each of these is good engineering. Each is also a different answer to the question of who owns your cluster's decisions.
Red Hat OpenShift
The complete platform — every layer decided, integrated and licensed per core. The ground BKE occupies with parts you can name, version and keep.
SUSE Rancher
A manager of many clusters with RKE2 underneath — strongest where the fleet is the problem, not the distribution.
VMware Tanzu
Kubernetes shaped to the vSphere estate, licensed accordingly. Compelling exactly as far as that estate extends.
Sidero Talos
An immutable, minimal OS-up distribution — a serious and different philosophy about what you should own, starting below the operating system.
For an estate already running on one of these platforms, the migration guides set out the method, and what each platform's objects and services require before a workload can move.
Documentation
The documentation, before you buy.
Everything an engineer needs to evaluate BKE is public — the same pages our customers operate from. Release notes and exact version pins accompany the licence, in the console.
01How a cluster fits together
Control planes, workers, and what each BKE command does on which machine. Start here if Kubernetes is new to you.
02Before you begin
What each machine needs, what BKE reaches over the network, and the three decisions you cannot change afterwards.
03Register your cluster
Binding a licence to the machine that will be your first control-plane node, before anything is installed.
04The first control-plane node
Creating the cluster — kubeadm init through install.sh on the first control-plane node, the three arguments fixed for its life, and what the script does.
05Adding nodes
Adding control-plane and worker nodes with two commands - one on an existing control-plane node, which prints the second, run on the new node.
06config.yaml
The one file that describes your cluster, key by key — components, Secrets, cluster login, encryption, reporting and compliance — and what each key's absence costs.
From the Journal
Announcements, press releases and articles.
The latest about BKE, published on the Mamluk Journal.
Announcement · 11 November 2026
Bahriya Kubernetes Engine 2.5.1 is released
BKE 2.5.1 brings Netdata v2.12.3, adds Netdata alarms for the Compliance App, and adds a check that Pods on every node can resolve cluster names. No node drains, and clusters on 2.5.0 upgrade with a single component apply.
Read on mamluk.net →Announcement · 9 November 2026
Bahriya Kubernetes Engine 2.5.0 is released
BKE 2.5.0 has every node hold BKE's kernel settings and modules at every boot, runs the kubelet with protectKernelDefaults on, and closes the audit log directory to other users. No node is drained.
Read on mamluk.net →Fourteen days, no sales motion
Evaluate it the way you would evaluate open source.
Create an account in the console, issue yourself a trial licence, and paste the registration command onto your first node. Nobody will call you — and the engine you evaluate is the one serving bahriya.cloud today.